Evaluators
Failures → Evaluators. Every check that grades your agent, in one list.
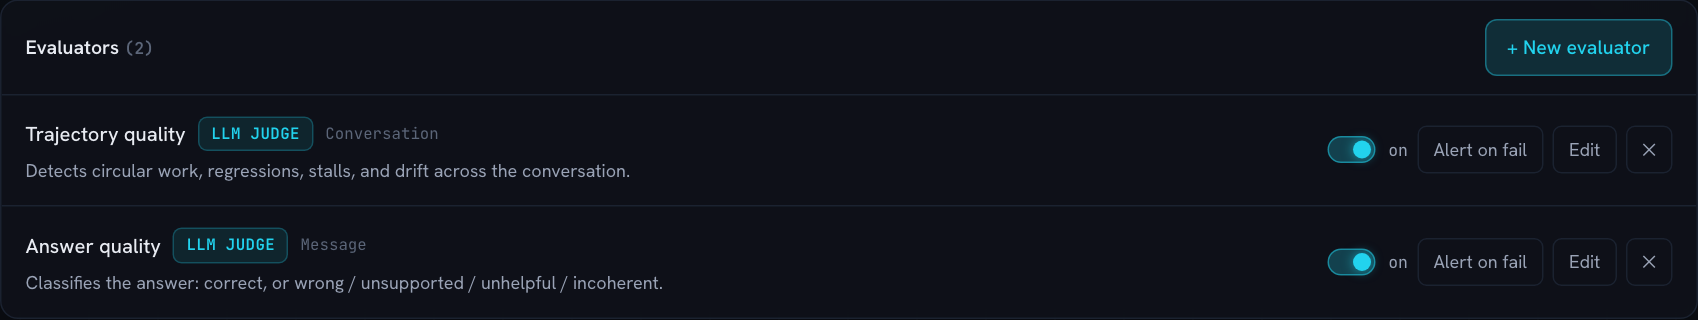
An evaluator is a column on the Traces table: every new trace is scored by every enabled evaluator a few seconds after ingest. This page is the same set of columns, managed without opening a grid first.
What a verdict does
A run fails iff some non-advisory evaluator scored it FAIL. That one rule drives everything
downstream:
- the red/green badge on the Traces table and the dashboard,
- failure clustering — only failed runs are clustered into issues,
- regression cases, which are promoted from those failures and replayed by the CI gate,
- the Conversation failed and FAIL rate triggers in Alerts.
Mark an evaluator advisory to keep its score visible without letting it fail a run.
Kinds and levels
| Kind | How it grades | Cost |
|---|---|---|
| Check (structural) | Deterministic, computed from the spans: run outcome, tool success, tool consistency, latency budget, required tools. | Free |
| LLM judge | A rubric graded by a model on the workspace’s own OpenRouter key (Settings → API keys). | Your tokens; capped by sampling |
The level says what one score is about: Conversation (the whole thread), Message (one request/answer) or Step (each tool call, generation or hand-off inside a message).
Managing evaluators
- + New evaluator opens the editor: start from the template library, write the rubric yourself, or describe the metric and let the model draft it. Every field is documented under Add Column — it is the same editor.
- Edit (or click the name) reopens it with the current configuration.
- The toggle stops an evaluator from grading new runs without deleting it or its past scores.
- ✕ deletes it; its column disappears from the Traces table. Deleting needs a signed-in account — an ingest key can send and read traces but never remove what people built.
Changing an evaluator grades new runs only. To re-score history, re-run the column from its header on the Traces table.
Alert on fail
Alert on fail opens a new alert already wired up: trigger Conversation failed, scoped to this evaluator, with a Slack step. Paste a Slack webhook URL (or swap the step for email or a webhook) and save. Use it for the evaluators you would want to hear about at 3 a.m. — a PII or policy judge, a tool-choice check — and leave the rest to the dashboard.
Trusting a judge
Before an LLM judge blocks merges, check it against yourself on Judge calibration: grade a sample blind and see how often the judge agrees, and whether it misses failures or over-flags.